SAN DIEGO. On November 19, Illumina said its BioInsight AI Lab won the 2026 Virtual Cell Challenge, hosted by Arc Institute. Of roughly 1,500 competitors, the company says, its predictions came closest to real experimental results across a wide range of biological measures.
The contest asked teams to predict what happens when a gene is knocked down in a cell line their models had never seen. Teams had only each cell's unperturbed state to work from. Arc scored the entries against hidden experimental data it generated itself.
For a company best known for selling DNA sequencers and reagents, the result is a statement about a different business: supplying the training data for AI biology.
The win is evidence that a large, standardized perturbation dataset helps a model generalize to cells it has not seen. It is not yet evidence that virtual cells find better drugs.
In This Story
- What Illumina won
- The algorithm is simpler than you might expect
- What the score actually says
- Open code, closed data
- Who else made the podium, and what it shows
- The data race: how the atlases compare
- Evidence Ladder
- What it means for health systems and investors
- Counter-thesis
- Forward Intelligence
What Illumina won
The entry paired two things. One is CellularAI, a new algorithm that predicts how a whole transcriptome responds to a genetic perturbation. The other is the Billion Cell Atlas, which Illumina calls the world's largest genome-wide genetic perturbation dataset. It records how individual cells respond to CRISPR edits across more than 200 disease-relevant cell lines.
Illumina is generating the atlas in a consortium with select pharmaceutical partners. It has not named them. Since announcing the atlas in January 2026, the company says its BioInsight AI Lab has sequenced more than 500 million single cells across multiple organ systems and disease types in nine months, with billions more planned.
First place paid $100,000, split between cash and NVIDIA Brev cloud credits, according to Arc.
NVIDIA sponsored the challenge and helped Arc build the scoring software. Second place paid $50,000 and third $25,000, on the same terms.
| Challenge fact | Detail | Source |
|---|---|---|
| Host | Arc Institute | Arc |
| Registrations | More than 5,441 | Arc |
| Teams on the validation leaderboard | 1,469 | Arc |
| Teams with a final entry | 805 | Arc |
| Task | Predict responses to 300 CRISPRi knockdowns in three held-out cell lines | Arc |
| Held-out cell lines | AC16 cardiomyocytes, MOLM13 acute myeloid leukemia, U-87MG glioblastoma | Arc |
| Prizes | $100,000, $50,000 and $25,000, cash plus | Arc |
| Winner | Illumina BioInsight AI Lab, final test score 0.4399 | Arc |
The algorithm is simpler than you might expect
CellularAI is not a giant neural network trained on the target cell type. By Illumina's own description, a meta-analysis sits at its core. It looks at how a gene responded when it was knocked down in other cell types, weights the evidence, corrects for measurement noise and traces each prediction back to the experiments it came from.
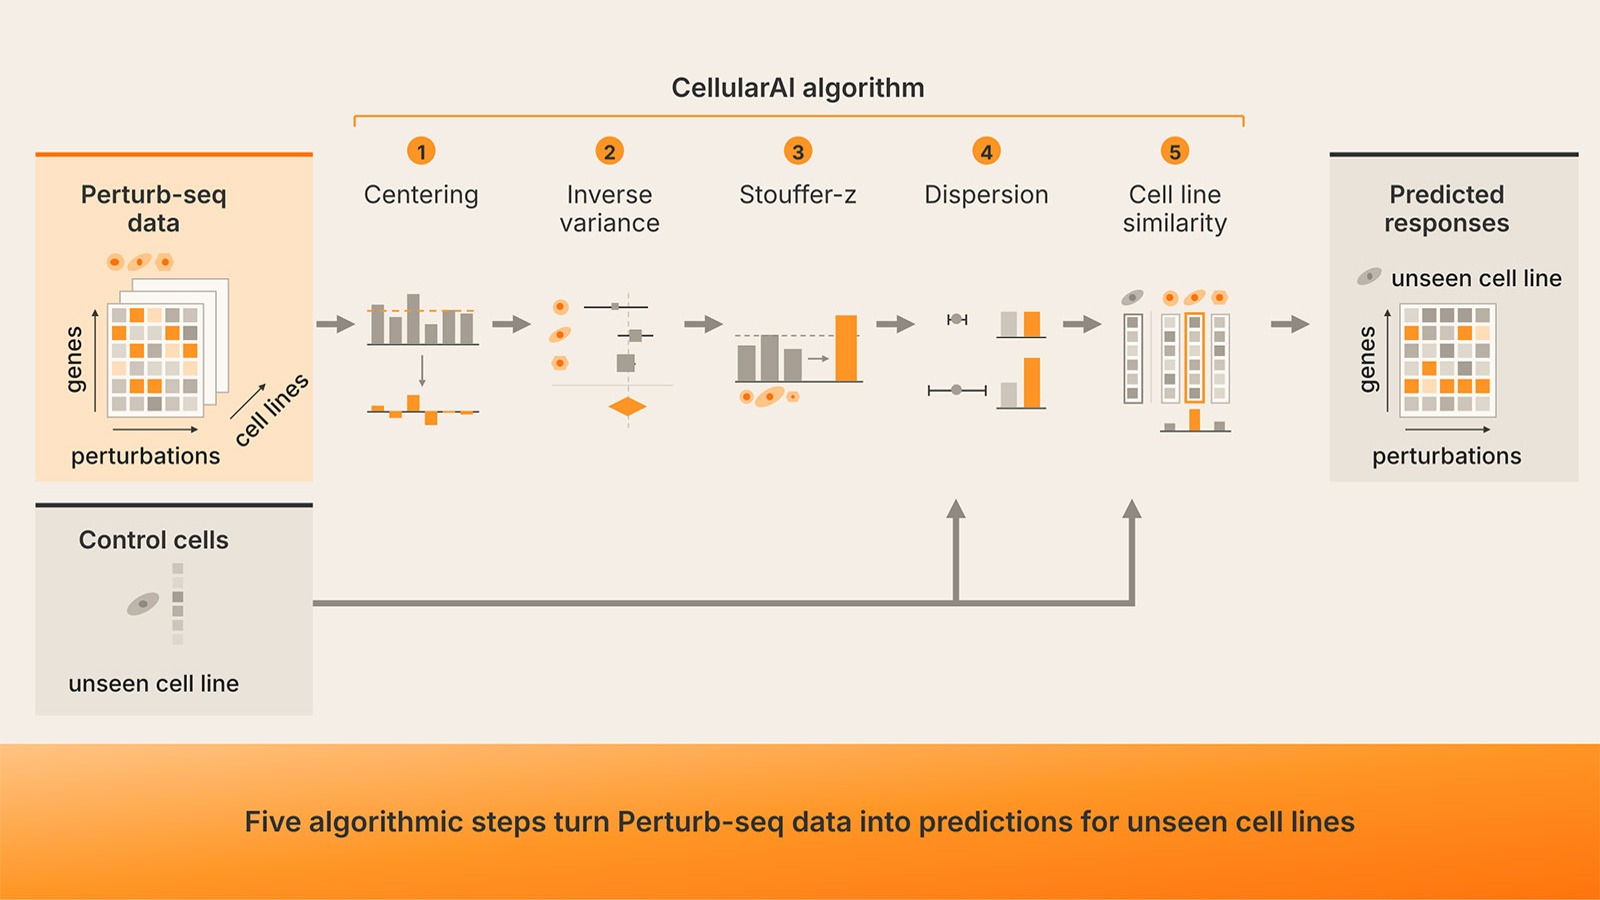
Arc's wrap-up describes the same design in more detail. The team estimated each knockdown's effect from several training datasets, combined them with a random-effects meta-analysis that weights each dataset by how closely its control cells resemble the new line, how noisy its estimates are and how efficient the knockdown was, then adapted the result to the new line and built 400 synthetic cells per knockdown from that line's own control cells. Training data included the Billion Cell Atlas and three published genome-scale CRISPRi datasets. The team also used LLM-based research agents running on eight NVIDIA H200 GPUs to tune the method, according to Arc.
That matters because this field has a credibility problem. Illumina's technical post notes that published perturbation models have struggled to beat a very basic baseline: the average expression across measured cells. The company reports that CellularAI performed about twice as well as that mean. Those figures are Illumina's. The challenge ranking, by contrast, rests on Arc's hidden data.
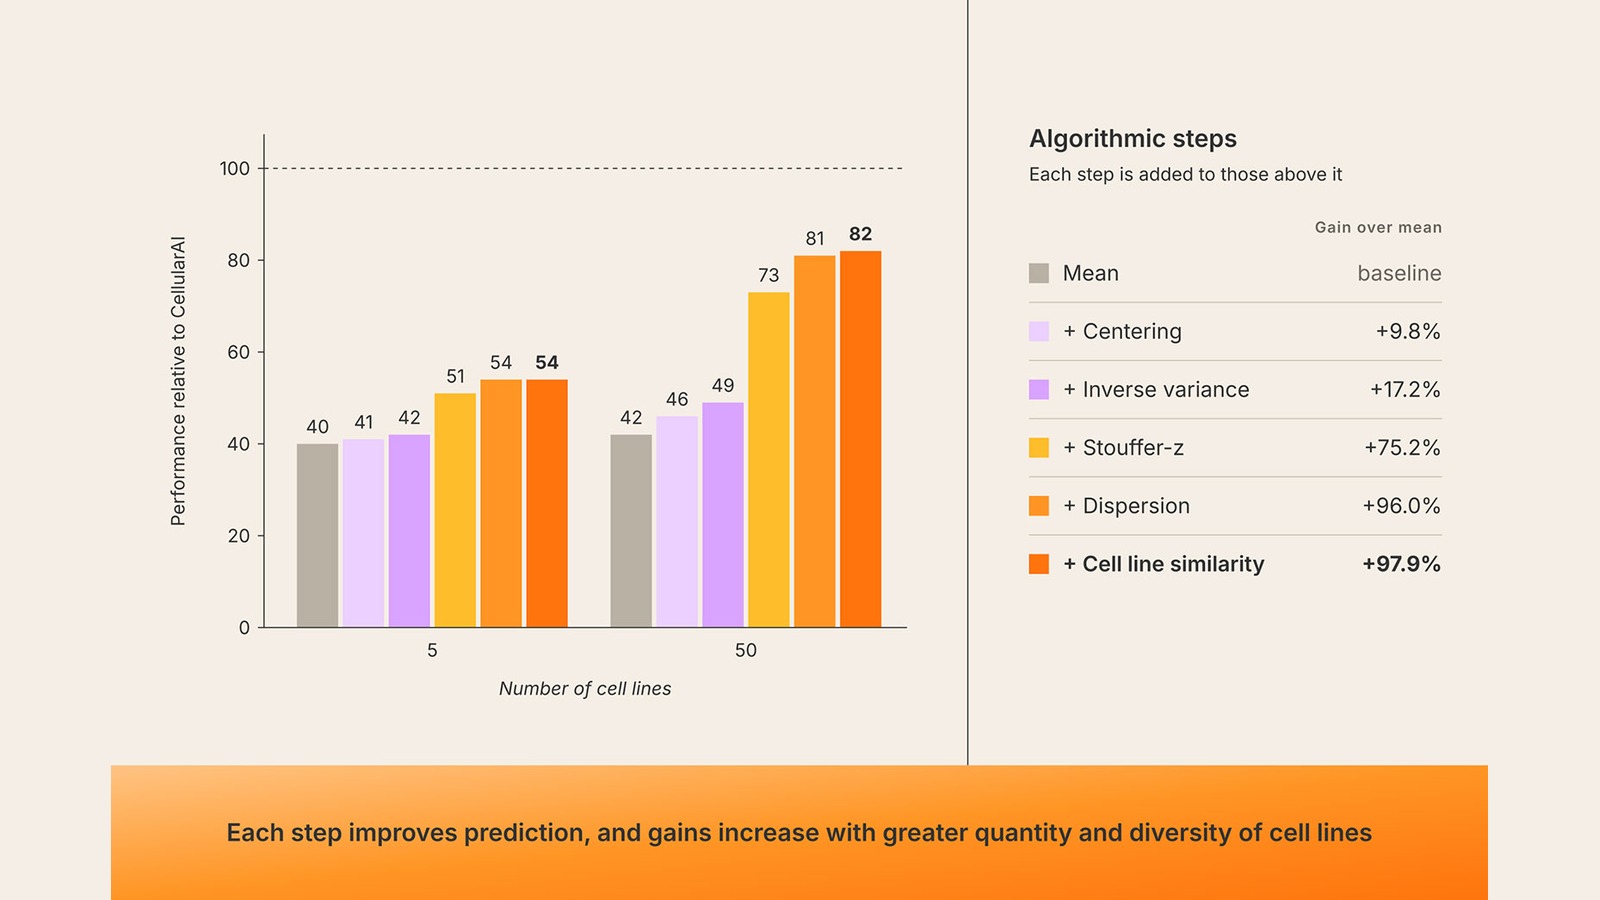
Illumina also shows which steps do the work. Each step is added to the ones above it, and the gains grow with the number of cell lines in the reference data.
| Algorithm step (cumulative) | Gain over mean | Performance relative to full CellularAI, 5 cell lines | Performance relative to full CellularAI, 50 cell lines |
|---|---|---|---|
| Mean baseline | Baseline | 40 | 42 |
| + Centering | +9.8% | 41 | 46 |
| + Inverse variance | +17.2% | 42 | 49 |
| + Stouffer-z | +75.2% | 51 | 73 |
| + Dispersion | +96.0% | 54 | 81 |
| + Cell line similarity | +97.9% | 54 | 82 |
Tier (A) for the figures, which are company-reported from Illumina's technical post. The number of cell lines in the reference set is the lever: with 50 lines the full pipeline reaches 82 on Illumina's scale, against 54 with five.
What the score actually says
Arc's own wrap-up is more cautious than a victory headline. The winning entry scored 0.440 on a scale where 0 is the average response across knockdowns and 1 is an independent replicate of the same experiment. Averaged over six metrics and three held-out cell lines, Arc says, the winning predictions covered 44% of the distance between that average and a replicate. Arc adds that the number does not represent accuracy and that individual metrics vary widely around it.
| Rank | Team | Final test score |
|---|---|---|
| 1 | BioInsight AI Lab (Illumina) | 0.4399 |
| 2 | FlowState | 0.3348 |
| 3 | X-team (Xaira Therapeutics) | 0.3263 |
| 4 | Obradovic Lab | 0.3243 |
| 5 | C-team | 0.3193 |
| 6 | Aginglab.com | 0.3175 |
| 7 | TAO | 0.3150 |
The lead is real, and so is its shape. Broken out by metric, Illumina led the three podium teams on four of the six measures and was edged on the other two.
| Metric | BioInsight AI Lab | FlowState | X-team |
|---|---|---|---|
| Overall | 0.4399 | 0.3348 | 0.3263 |
| PDS | 0.8313 | 0.8363 | 0.7346 |
| MSE | 0.6842 | 0.3632 | 0.4681 |
| NMAE | 0.4399 | 0.3286 | 0.3038 |
| FIDELITY | 0.1908 | 0.1695 | 0.0659 |
| REACH | 0.4288 | 0.3128 | 0.3186 |
| JACCARD | 0.0642 | -0.0018 | 0.0667 |
Scores are scaled within each cell line, with the cell context mean at 0 and a replicate of the real data at 1. PDS is the one metric where FlowState edged ahead, and X-team scored highest on JACCARD, where even the best entry scored only about 0.07.
The field was large. Arc reports more than 5,441 registrations, 1,469 teams on the validation leaderboard and 805 teams with a final entry. That is the context for Illumina's figure of roughly 1,500 competitors.
This year's task was harder than the 2025 version. Teams got no training set from the target lines, only unperturbed control cells for each, and had to predict the response to 300 CRISPRi knockdowns in three held-out lines. Zero-shot has a limit here. Arc notes that teams could train on any public or private data, and that all but one of the 300 test targets already had public perturbation data in some other cell line. Simply carrying those measured responses over to a new line, with no learning at all, recovers a large part of the signal, Arc says.
Arc's analysis of where the models fell short is the part to read twice.
| Reality check | Measured | Models |
|---|---|---|
| Similarity of the response to one knockdown across cell lines (cosine) | 0.55 | 0.77 to 0.89 for the top ten entries |
| Significant genes per target on the validation lines | Median 22 to 44 | X-team 122 to 136; Illumina about 500 |
Arc concludes that current models recover roughly what a cross-line average would predict, while the part of the response that is specific to a cell line is still largely missing. That line-specific part is exactly what a virtual cell would need to improve on an experiment in another model system. The models also over-called, predicting many more responding genes than the experiments found.
Open code, closed data
Illumina released a first, streamlined open-source version of CellularAI on the same day, on GitHub. The release does not include the Billion Cell Atlas, and the open version was not trained on it. Researchers can run the method on their own compatible reference data. Only the atlas consortium partners get to use it with the largest reference library Illumina has built.
That is a familiar platform move: share the method, keep the input. Every additional cell sequenced for the atlas also consumes Illumina's own single cell chemistry, which is why the data play fits the company's core business.
Who else made the podium, and what it shows
| Place | Team | Who | Data | Approach |
|---|---|---|---|---|
| 1 | BioInsight AI Lab | Illumina | Billion Cell Atlas plus three published CRISPRi datasets | CellularAI, a meta-analysis of other cell types |
| 2 | FlowState | Sina Khodaveisi and Navid Bagheri, independent researchers | Public data only: 222 perturbation-response datasets from 128 studies, 86 cellular contexts | Modular pipeline transferring measured effects |
| 3 | X-team | Xaira Therapeutics | In-house and external Perturb-seq data, more than 37 million cells | X-Cell, a masked diffusion model, used to choose which measured effects to carry over |
Second place went to FlowState, two independent researchers. They used public data only. Third place went to X-team from Xaira Therapeutics, which built its entry around X-Cell, trained on more than 37 million cells, according to Arc. It was the only foundation model on the podium, and the team used it to decide which measured effects to carry into the new line rather than to generate cells directly.
Arc's reading is that all three winners built modular pipelines, not single end-to-end models. Each estimated a knockdown's effect from other cell types, adapted it using the new line's controls, then generated the cells. Arc says reference data and how carefully it is transferred matter at least as much as model architecture, for now, though it notes that ablation studies are needed to confirm that. It also says a podium finish did not require private data, since FlowState placed second on public data alone. Because open weights and code were not required this year, the team descriptions rely on what each team supplied.
Ion Genomics, a trade newsletter, adds that corporate-backed teams topped the leaderboard, with a Novo Nordisk Foundation team in fifth place and South Korea's AgingLab in sixth. It also reports that the Illumina team used over 200 million perturbed cells from 57 cell lines to build CellularAI.
The data race: how the atlases compare
Start with the buyer. A target discovery group at a drugmaker has a familiar problem: genetics points to a gene, but proving it matters in the right cell type costs months of CRISPR work. Rami Mehio, Illumina's senior vice president and general manager of BioInsight, said the atlas is positioned to help with drug discovery, drug repurposing and understanding mechanism of action. This result does not show any of that yet. It shows that a large, diverse perturbation dataset helps a model generalize to cell types it has not seen. That is a necessary step, not the finish.
The competitive picture is a race over data.
| Dataset | Owner | Scale | Access | Strategic position |
|---|---|---|---|---|
| Billion Cell Atlas | Illumina | More than 500 million cells sequenced since January 2026; more than 200 disease-relevant cell lines | Paying consortium of select pharma partners; names undisclosed | Largest genome-wide perturbation dataset, kept private; method given away |
| X-Atlas/Orion | Xaira Therapeutics | About 8 million cells, two screens in HCT116 and HEK293T, 18,903 genes targeted | Free for non-commercial use; open to commercial collaborations | Models and data built together, attacking from the drug program end |
| Tahoe-100M | Tahoe | More than 100 million cells, 50 cancer cell lines, over 1,100 drug treatments | CC0 license, hosted in Arc's Virtual Cell Atlas | Open data that lowers everyone's entry cost |
| Arc challenge data | Arc Institute | More than 30 million deeply sequenced cells across six cell lines | Used as the hidden test set | Neutral host and benchmark |
Illumina's bet is the opposite of open. It is keeping the largest atlas inside a paying consortium and giving away the method. FlowState's second place is the awkward fact for that strategy. If carefully harmonized public data can sit near the top of a leaderboard against large private atlases, the moat has to come from something the public sets lack, such as breadth across more than 200 cell lines, consistency and scale. Illumina's team says its model worked because of the depth, diversity and quality of the atlas, and the next challenge will test that claim.
There is a second layer. The instruments in this race are not exclusively Illumina's. Xaira's atlas was sequenced on Illumina NovaSeq X Plus instruments, according to its preprint, while Arc says it used 10x Genomics Flex and Ultima Genomics UG100 platforms for this year's data, and its Virtual Cell Atlas credits Ultima for sequencing Tahoe-100M. Seen that way, owning a proprietary dataset is a way for Illumina to turn a contested sequencing market into a data business.
Regulation is a tailwind, though a narrow one. In April 2025 the FDA published a roadmap to reduce animal testing in preclinical safety studies, starting with monoclonal antibodies and encouraging sponsors to submit data from new approach methodologies, which include AI-based computational models. That policy concerns safety and toxicity, not target discovery, so it does not make a virtual cell a regulatory tool. It does show the agency is open to computational evidence, which helps every company in this field.
Evidence Ladder
- Physics: not the constraint. Gene knockdown and single-cell sequencing are established methods; the question is scale and consistency.
- Lab proof: established for the data method. Illumina reports more than 500 million cells sequenced for the atlas.
- Real-world: early. A blind challenge win on held-out cell lines is the strongest public evidence so far that CellularAI generalizes, but it is one benchmark and the winning score covers 44% of the gap to a replicate.
- Clinical validation: absent. No drug target or program has been publicly attributed to the atlas or CellularAI.
- Reimbursement: not applicable. The economics run through research budgets and consortium fees, not payers.
Tier (A) for the rungs supported by Illumina's and Arc's disclosures; Tier (B) for our placement of the result on the ladder.
What it means for health systems and investors
For health systems, the honest answer is that nothing changes at the bedside this year. The effect, if it comes, arrives through the drug pipeline: better target selection could, in time, improve the odds that new drugs reach patients. Hospital research institutes and academic centers are closer to it, as possible data partners and as buyers of the tools. The questions to ask are practical ones: what the license terms are, whether results can be reproduced with the open code, and how patient-derived samples are governed if they feed commercial atlases.
For investors, this is a story about who captures value in a stack. Data generators sit at the bottom, model builders in the middle and drug programs at the top. Illumina wants the bottom layer and influence over the middle through open code. Xaira is attacking from the top with models and its own atlases. Tahoe and Arc are pushing open data that lowers everyone's entry cost. What is missing from the public record is the part investors would want most: what consortium partners pay, how long contracts run, and how much revenue the atlas adds to a company that sells instruments and reagents. Illumina has not disclosed any of it.
The HealthTech Investor's Signal
We read the win as validation of a data strategy rather than a single model. Investors evaluating Illumina should watch for disclosed consortium partners and any revenue line tied to BioInsight. A named pharma partner citing the atlas in a target decision would be a meaningful step. For private AI biology companies, the bar for differentiation rises: expect diligence questions about performance on unseen cell types and against simple baselines, and about the provenance and rights of training data.
This is not a recommendation to buy or sell any security.
Counter-thesis
The first objection is that benchmarks are not drug programs. A model that matches the cross-line average well can win a leaderboard and still miss what makes one cell type behave differently from another. Arc's own figures show that gap: a 44% score, and about 500 genes called against a measured 22 to 44.
The second is that the evidence for the algorithm is partly company-reported. The 2X improvement over the mean is Illumina's figure. The open-source version is a simplified release that was not trained on the atlas, so outside labs cannot yet reproduce the winning setup. Arc also notes that final ranks reflect some re-uploads, though it found the gains small.
The third is that the commercial terms are opaque. Illumina has not named its consortium partners or said what access costs. It has not said whether any drug target or program has come out of the atlas. A full manuscript on the method is due in early 2027.
Forward Intelligence
- Named consortium partners for the Billion Cell Atlas, and the terms of access.
- Independent groups reproducing CellularAI's gains with the open-source code.
- New data from Xaira, Tahoe or Arc that narrows the gap.
- A pharma partner attributing a target selection or program decision to atlas data or CellularAI.
- Illumina's full manuscript, due in early 2027, and the next Virtual Cell Challenge, which Arc says returns next summer.
The Bottom Line for Pharma R&D Leaders, Health Systems and Investors
What changed this week is that a large, standardized perturbation dataset helped a model win a blind test on cell lines it had never seen, in a field where beating a simple average has been hard. Illumina is using that result to sell access to the data, while giving away an initial version of the algorithm. That is a sensible strategy for a company whose instruments generate the data in the first place.
What remains uncertain is whether better predictions of gene expression lead to better targets and fewer failed programs. For R&D leaders, the practical step is to test the open-source model on internal data and ask consortium questions about coverage and rights. For investors, treat the win as evidence of a credible data platform, not yet of drug discovery value, until a partner ties a program to it.
Sources
- Illumina release (PR Newswire), November 19, 2026
- Illumina: Introducing the CellularAI algorithm
- CellularAI open-source code (GitHub)
- Arc Institute: Virtual Cell Challenge 2026 winners and wrap-up
- Ion Genomics: Illumina tops AI cell challenge, but models struggle to predict biology
- Xaira Therapeutics: X-Atlas/Orion release, June 17, 2025
- X-Atlas/Orion preprint (bioRxiv)
- Arc Virtual Cell Atlas and Tahoe-100M
- FDA: plan to phase out animal testing requirement for monoclonal antibodies and other drugs, April 10, 2025